packaging: jar<dependencies>
<!-- 核心包 -->
<dependency>
<groupId>org.apache.lucene</groupId>
<artifactId>lucene-core</artifactId>
<version>5.5.3</version>
</dependency>
<!-- 查詢解析器 -->
<dependency>
<groupId>org.apache.lucene</groupId>
<artifactId>lucene-queryparser</artifactId>
<version>5.5.3</version>
</dependency>
<!-- 標準分詞器 -->
<dependency>
<groupId>org.apache.lucene</groupId>
<artifactId>lucene-analyzers-common</artifactId>
<version>5.5.3</version>
</dependency>
</dependencies>
<build>
<plugins>
<plugin>
<groupId>org.apache.maven.plugins</groupId>
<artifactId>maven-compiler-plugin</artifactId>
<version>3.3</version>
<configuration>
<source>1.7</source>
<target>1.7</target>
</configuration>
</plugin>
</plugins>
</build>
import java.io.File;
import java.io.FileReader;
import java.nio.file.Paths;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.FSDirectory;

public class Indexer {
    private IndexWriter writer;

    public Indexer(String indexDir) throws Exception {
        Directory dir = FSDirectory.open(Paths.get(indexDir));
        Analyzer analyzer = new StandardAnalyzer();
        IndexWriterConfig iwc = new IndexWriterConfig(analyzer);
        writer = new IndexWriter(dir, iwc);
    }

    public void close() throws Exception { writer.close(); }

    public int index(String dataDir) throws Exception {
        File[] files = new File(dataDir).listFiles();
        for (File f : files) indexFile(f);
        return writer.numDocs();
    }

    private void indexFile(File f) throws Exception {
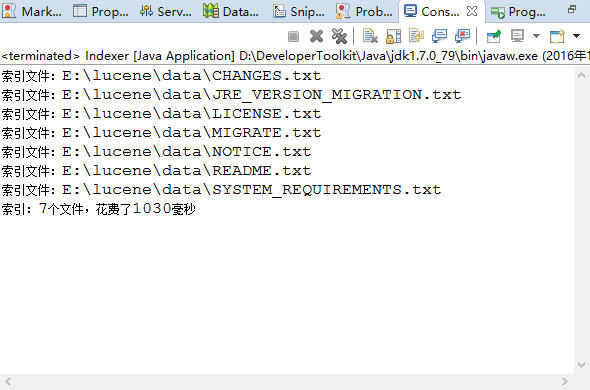
        System.out.println("索引文件:" + f.getCanonicalPath());
        Document doc = getDocument(f);
        writer.addDocument(doc);
    }

    private Document getDocument(File f) throws Exception {
        Document doc = new Document();
        // 內容:不存儲,只分詞索引
        doc.add(new TextField("contents", new FileReader(f)));
        // 文件名:存儲
        doc.add(new TextField("fileName", f.getName(), Field.Store.YES));
        // 完整路徑:存儲
        doc.add(new TextField("fullPath", f.getCanonicalPath(), Field.Store.YES));
        return doc;
    }

    public static void main(String[] args) {
        String indexDir = "E:\\lucene";
        String dataDir = "E:\\lucene\\data";
        Indexer indexer = null;
        int numIndexed = 0;
        long start = System.currentTimeMillis();
        try {
            indexer = new Indexer(indexDir);
            numIndexed = indexer.index(dataDir);
        } catch (Exception e) { e.printStackTrace(); }
        finally { try { indexer.close(); } catch (Exception e) { e.printStackTrace(); } }
        long end = System.currentTimeMillis();
        System.out.println("索引:" + numIndexed + " 個文件,耗時 " + (end - start) + " 毫秒");
    }
}
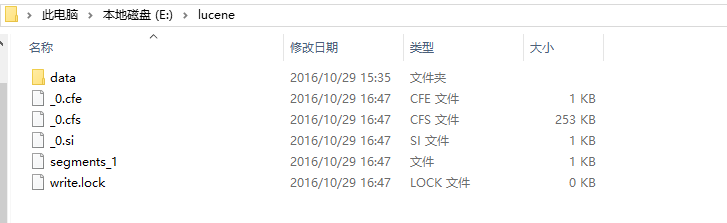
運行前準備: 在任意盤符創建 lucene/data 目錄,放入若干 .txt 文件測試。
索引目錄下生成文件:
import java.nio.file.Paths;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexReader;
import org.apache.lucene.queryparser.classic.QueryParser;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.ScoreDoc;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.FSDirectory;

public class Searcher {
    public static void search(String indexDir, String q) throws Exception {
        Directory dir = FSDirectory.open(Paths.get(indexDir));
        IndexReader reader = DirectoryReader.open(dir);
        IndexSearcher is = new IndexSearcher(reader);
        Analyzer analyzer = new StandardAnalyzer();
        QueryParser parser = new QueryParser("contents", analyzer);
        Query query = parser.parse(q);

        long start = System.currentTimeMillis();
        TopDocs hits = is.search(query, 10); // 取前 10
        long end = System.currentTimeMillis();

        System.out.println("查詢 \"" + q + "\",耗時 " + (end - start) + "ms,命中 " + hits.totalHits + " 條");
        for (ScoreDoc sd : hits.scoreDocs) {
            Document doc = is.doc(sd.doc);
            System.out.println(doc.get("fullPath"));
        }
        reader.close();
    }

    public static void main(String[] args) {
        String indexDir = "E:\\lucene";
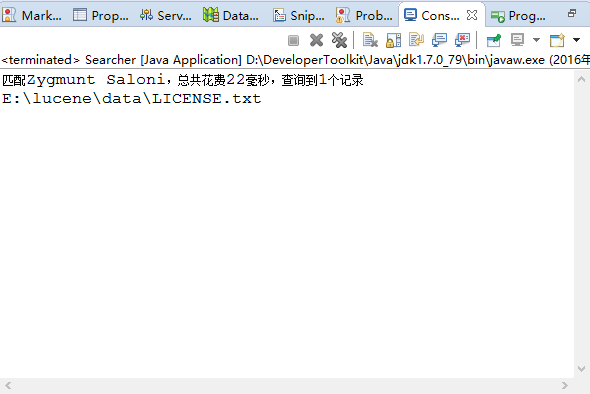
        String q = "Zygmunt Saloni"; // 測試關鍵詞
        try { search(indexDir, q); } catch (Exception e) { e.printStackTrace(); }
    }
}
FSDirectory 文件系統、RAMDirectory 內存)StandardAnalyzer 標準、IKAnalyzer 中文)TextField 分詞索引,StringField 不分詞精確匹配,StoredField 僅存儲addDocument/deleteDocuments/updateDocumentsearch(Query, n) 返回 TopDocsIndexNotFoundException)TextField 內容不存儲(Store.NO),需顯示內容請另加 StoredFieldNearRealTime (NRT) 搜尋,避免頻繁 commit轉載請注明出處。博客園:https://www.cnblogs.com/tenglongwentian/