| 特性 | ArrayList (List) | HashSet (Set) |
|---|---|---|
| 有序性 | 有序:按添加順序維護索引位置 | 無序:基於哈希值分佈,迭代順序不固定 |
| 重復性 | 可重復:equals() 為 true 也可共存 | 不可重復:equals() 為 true 視為同一元素 |
| 底層結構 | 動態數組 Object[] elementData | HashMapmap(Key 存元素,Value 固定 PRESENT) |
| 隨機訪問 | O(1) get(index) | 不支持索引訪問 |
| 查找/插入/刪除 | O(n) 線性掃描 | O(1) 平均(依賴 hashCode 分佈均勻) |
| 空元素 | 允許任意多個 null | 允許一個 null |
List<Integer> list = new ArrayList<>();
Set<Integer> set = new HashSet<>();
Arrays.asList(1,2,0,3,2,1,3,5,0).forEach(n -> { list.add(n); set.add(n); });

System.out.println("ArrayList: " + list); // [1, 2, 0, 3, 2, 1, 3, 5, 0] 保留順序與重復
System.out.println("HashSet:   " + set);   // [0, 1, 2, 3, 5]       去重、無序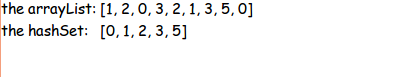
所以 new Integer(1).equals(new Integer(1)) == true,HashSet 能正確去重。自定義類若未重寫 equals/hashCode,HashSet 將按引用地址判斷,失去去重功能。
List<Integer> distinct = new ArrayList<>(new LinkedHashSet<>(list));LinkedHashSet 維護雙向鏈表記錄插入順序,同時具備 Set 去重特性public static void rmRepeatedElementByOrder(List<Integer> list) {
Set<Integer> seen = new HashSet<>();
List<Integer> result = new ArrayList<>();
for (Integer e : list) {
if (seen.add(e)) { // add 返回 true 表示首次見到
result.add(e);
}
}
list.clear();
list.addAll(result);
}List<Integer> distinct = list.stream().distinct().collect(Collectors.toList());parallelStream() 去重結果順序不保證| 場景 | 推薦集合 | 理由 |
|---|---|---|
| 頻繁隨機訪問、末尾增刪 | ArrayList | 數組結構,緩存友好 |
| 頻繁頭部/中間增刪 | LinkedList | 鏈表結構,無需數組擴容/位移 |
| 高頻查找、去重、集合運算 | HashSet | 哈希表 O(1) 查找 |
| 去重且需保持插入順序 | LinkedHashSet | 哈希+雙向鏈表 |
| 有序集合、範圍查詢 | TreeSet | 紅黑樹,自然序/比較器序 |
| 多線程環境 | CopyOnWriteArrayList / ConcurrentHashMap.keySet() | 線程安全讀多寫少 / 高並發 |
ArrayList.remove(Object) 遍歷刪除易導致 ConcurrentModificationException,請用 Iterator.remove() 或反向循環。HashSet 非線程安全,多線程請用 Collections.synchronizedSet() 或 ConcurrentHashMap.newKeySet()。Bloom Filter(布隆過濾器)預過濾,減少內存壓力。集合選型無銀彈,理解底層數據結構與複雜度,根據業務訪問模式決策,才是架構師思維。