中文亂碼本質是編碼不一致。Java內部用UTF-16,I/O按OS默認編碼。跨平台、多組件鏈路下,必須全鏈路強制指定UTF-8。
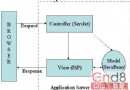
瀏覽器(OS編碼) → Request → Servlet/JSP(OS編碼) → JVM(UTF-16) → 業務邏輯
                                    ↓
                              數據庫(各自編碼)
                                    ↓
                              Response(OS編碼) → 瀏覽器
任意環節編碼不匹配即產生亂碼。
new String(bytes, "GBK"),不可維護IDE項目編碼設置為UTF-8(Eclipse:Properties→Resource→Text file encoding;IntelliJ:Settings→File Encodings)。
Filter統一設置(最早執行):
public class EncodingFilter implements Filter {
    public void doFilter(ServletRequest req, ServletResponse resp, FilterChain chain) {
        req.setCharacterEncoding("UTF-8");
        resp.setCharacterEncoding("UTF-8");
        chain.doFilter(req, resp);
    }
}web.xml配置<filter-mapping>覆蓋所有/*。
<%@ page contentType="text/html;charset=UTF-8" pageEncoding="UTF-8" %>
<meta http-equiv="Content-Type" content="text/html; charset=UTF-8" />MySQL JDBC URL:
jdbc:mysql://localhost:3306/db?useUnicode=true&characterEncoding=UTF-8Oracle/PostgreSQL/SQL Server均有相應連接屬性或Session參數設置UTF-8。
new InputStreamReader(new FileInputStream(f), "UTF-8")<?xml encoding="UTF-8"?>,解析器默認UTF-8Properties.load(Reader)指定編碼Struts 2、Spring MVC、Tapestry、Hibernate、Jdon等主流框架均無縫支持UTF-8全鏈路,一次配置終身受益。