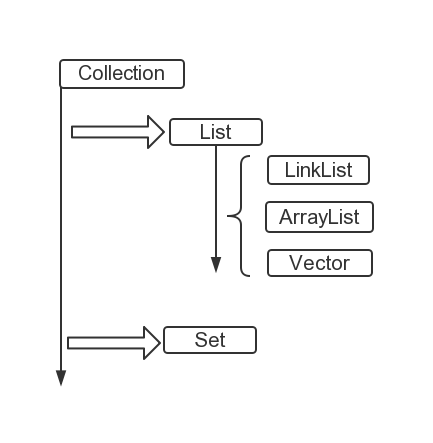
Set 不允許重複元素,若陣列長度與 Set.size() 不等,則存在重複。
public static boolean hasNoDuplicates(String[] array) {
    if (array == null) return true;  // 或拋異常視業務而定
    Set set = new HashSet<>(Arrays.asList(array));
    return set.size() == array.length;
}

// 呼叫範例
String[] arr = {"a", "b", "c", "a"};
System.out.println(hasNoDuplicates(arr)); // false(有重複) public static boolean hasNoDuplicates(String[] array) {
return array != null && Arrays.stream(array).distinct().count() == array.length;
}
// 或直接收集到 Set
public static boolean hasNoDuplicates(String[] array) {
return array != null && new HashSet<>(Arrays.asList(array)).size() == array.length;
}public static Set findDuplicates(String[] array) {
Set seen = new HashSet<>();
Set duplicates = new HashSet<>();
for (String s : array) {
if (!seen.add(s)) { // add 回傳 false 表示已存在
duplicates.add(s);
}
}
return duplicates;
}
// Stream 版
public static Set findDuplicates(String[] array) {
return Arrays.stream(array)
.collect(Collectors.groupingBy(Function.identity(), Collectors.counting()))
.entrySet().stream()
.filter(e -> e.getValue() > 1)
.map(Map.Entry::getKey)
.collect(Collectors.toSet());
} | 方法 | 時間複雜度 | 空間複雜度 | 備註 |
|---|---|---|---|
| HashSet 去重 | O(N) | O(N) | 最通用、效能最佳 |
| 排序後相鄰比較 | O(N log N) | O(1) 或 O(N) | 不想用額外空間時可考慮 |
| 雙重迴圈 | O(N²) | O(1) | 僅適合極小陣列 (N<50) |
若為 int[]、long[] 等基本型別,避免裝箱開銷:
// 使用 primitive 集合庫(如 Eclipse Collections、FastUtil)或排序法
public static boolean hasDuplicateInt(int[] arr) {
    Arrays.sort(arr);
    for (int i = 1; i < arr.length; i++) {
        if (arr[i] == arr[i-1]) return true;
    }
    return false;
}new HashSet<>(Arrays.asList(arr)).size() == arr.length 一行搞定seen.add() 回傳值或 Stream groupingBynull 算不算重複,統一規範