生產環境 MySQL CPU 飆升至 36,mysqladmin processlist 顯示大量 SELECT * FROM rep_corp_vehicle_online_count WHERE corp_id = ? AND vehicle_id = ? 全表掃描。本文完整復盤從現象觀測、表結構分析、數據分佈掃描、EXPLAIN 計劃對比、創建複合索引到負載驟降的全過程。
現象:CPU 負載 36,大量慢查詢堵塞。
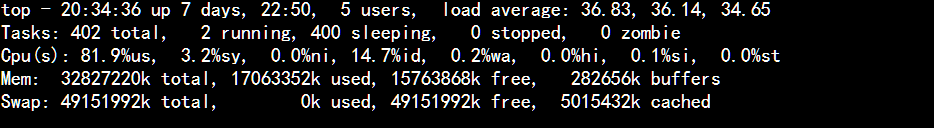
進程列表:
Sending data select * from `rep_corp_vehicle_online_count` where corp_id = 48 and vehicle_id = 10017543
DESC rep_corp_vehicle_online_count;
+-------------+-------------+------+-----+---------+----------------+
| Field       | Type        | Null | Key | Default | Extra          |
+-------------+-------------+------+-----+---------+----------------+
| id          | int(11)     | NO   | PRI | NULL    | auto_increment |
| corp_id     | int(11)     | NO   |     | NULL    |                |
| vehicle_id  | int(11)     | NO   |     | NULL    |                |
| online_day  | varchar(20) | NO   |     | NULL    |                |
| loc_total   | int(11)     | NO   |     | NULL    |                |
| create_time | datetime    | NO   |     | NULL    |                |
| update_time | datetime    | NO   |     | NULL    |                |
+-------------+-------------+------+-----+---------+----------------+
現有索引:僅主鍵 PRIMARY KEY (id)。
SHOW INDEX FROM rep_corp_vehicle_online_count;
+-------------------------------+------------+----------+--------------+-------------+-----------+-------------+----------+--------+------+------------+---------+---------------+
| Table                         | Non_unique | Key_name | Seq_in_index | Column_name | Collation | Cardinality | Sub_part | Packed | Null | Index_type | Comment | Index_comment |
+-------------------------------+------------+----------+--------------+-------------+-----------+-------------+----------+--------+------+------------+---------+---------------+
| rep_corp_vehicle_online_count | 0          | PRIMARY  | 1            | id          | A         | 1247259     | NULL     | NULL   |      | BTREE      |         |               |
+-------------------------------+------------+----------+--------------+-------------+-----------+-------------+----------+--------+------+------------+---------+---------------+
EXPLAIN SELECT * FROM rep_corp_vehicle_online_count
WHERE corp_id = 79 AND vehicle_id = 10016911 AND online_day = '2016-03-29'\G
*************************** 1. row ***************************
id: 1
select_type: SIMPLE
table: rep_corp_vehicle_online_count
type: ALL                    -- 全表掃描
possible_keys: NULL
key: NULL
key_len: NULL
ref: NULL
rows: 1248495                -- 掃描 124 萬行
Extra: Using where
1 row in set (0.00 sec)
-- corp_id 僅 18 個不同值,極低基數
SELECT COUNT(DISTINCT corp_id) FROM rep_corp_vehicle_online_count; -- 18
SELECT COUNT(corp_id) FROM rep_corp_vehicle_online_count;          -- 123 萬

-- vehicle_id 2580 個不同值,中等基數
SELECT COUNT(DISTINCT vehicle_id) FROM rep_corp_vehicle_online_count; -- 2580
SELECT COUNT(vehicle_id) FROM rep_corp_vehicle_online_count;         -- 123 萬
結論:corp_id 區分度極低(18 個值),單列索引效果差;vehicle_id 區分度中等。組合索引 (corp_id, vehicle_id) 可先按 corp_id 過濾到少量分區,再按 vehicle_id 精確定位,效果最佳。
CREATE INDEX r_c_v ON rep_corp_vehicle_online_count(corp_id, vehicle_id);
Query OK, 1487993 rows affected (6.09 sec)
索引創建後結構:
SHOW INDEX FROM rep_corp_vehicle_online_count;
+-------------------------------+------------+----------+--------------+-------------+-----------+-------------+----------+--------+------+------------+---------+---------------+
| Table                         | Non_unique | Key_name | Seq_in_index | Column_name | Collation | Cardinality | Sub_part | Packed | Null | Index_type | Comment | Index_comment |
+-------------------------------+------------+----------+--------------+-------------+-----------+-------------+----------+--------+------+------------+---------+---------------+
| rep_corp_vehicle_online_count | 0          | PRIMARY  | 1            | id          | A         | 1490176     | NULL     | NULL   |      | BTREE      |         |               |
| rep_corp_vehicle_online_count | 1          | r_c_v    | 1            | corp_id     | A         | 18          | NULL     | NULL   |      | BTREE      |         |               |
| rep_corp_vehicle_online_count | 1          | r_c_v    | 2            | vehicle_id  | A         | 2596        | NULL     | NULL   |      | BTREE      |         |               |
+-------------------------------+------------+----------+--------------+-------------+-----------+-------------+----------+--------+------+------------+---------+---------------+
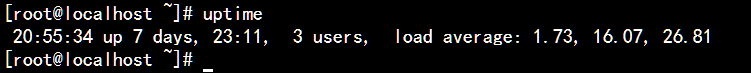
同樣 SQL 現走 ref 類型,掃描行數從 124 萬降至預估個位數,CPU 負載瞬間回落。
processlist + EXPLAIN 定位全表掃描 SQL。COUNT(DISTINCT col) 判斷基數,低基數列靠前組合高基數列。(corp_id, vehicle_id) 支持 WHERE corp_id=?、WHERE corp_id=? AND vehicle_id=?,不支持單獨 vehicle_id。pt-online-schema-change 或 gh-ost 在線變更,避免鎖表阻塞業務。一條精準的複合索引,抵得上十台服務器擴容。索引優化,是性價比最高的 MySQL 調優手段。